Parallel corpora as infrastructure for natively localized AI
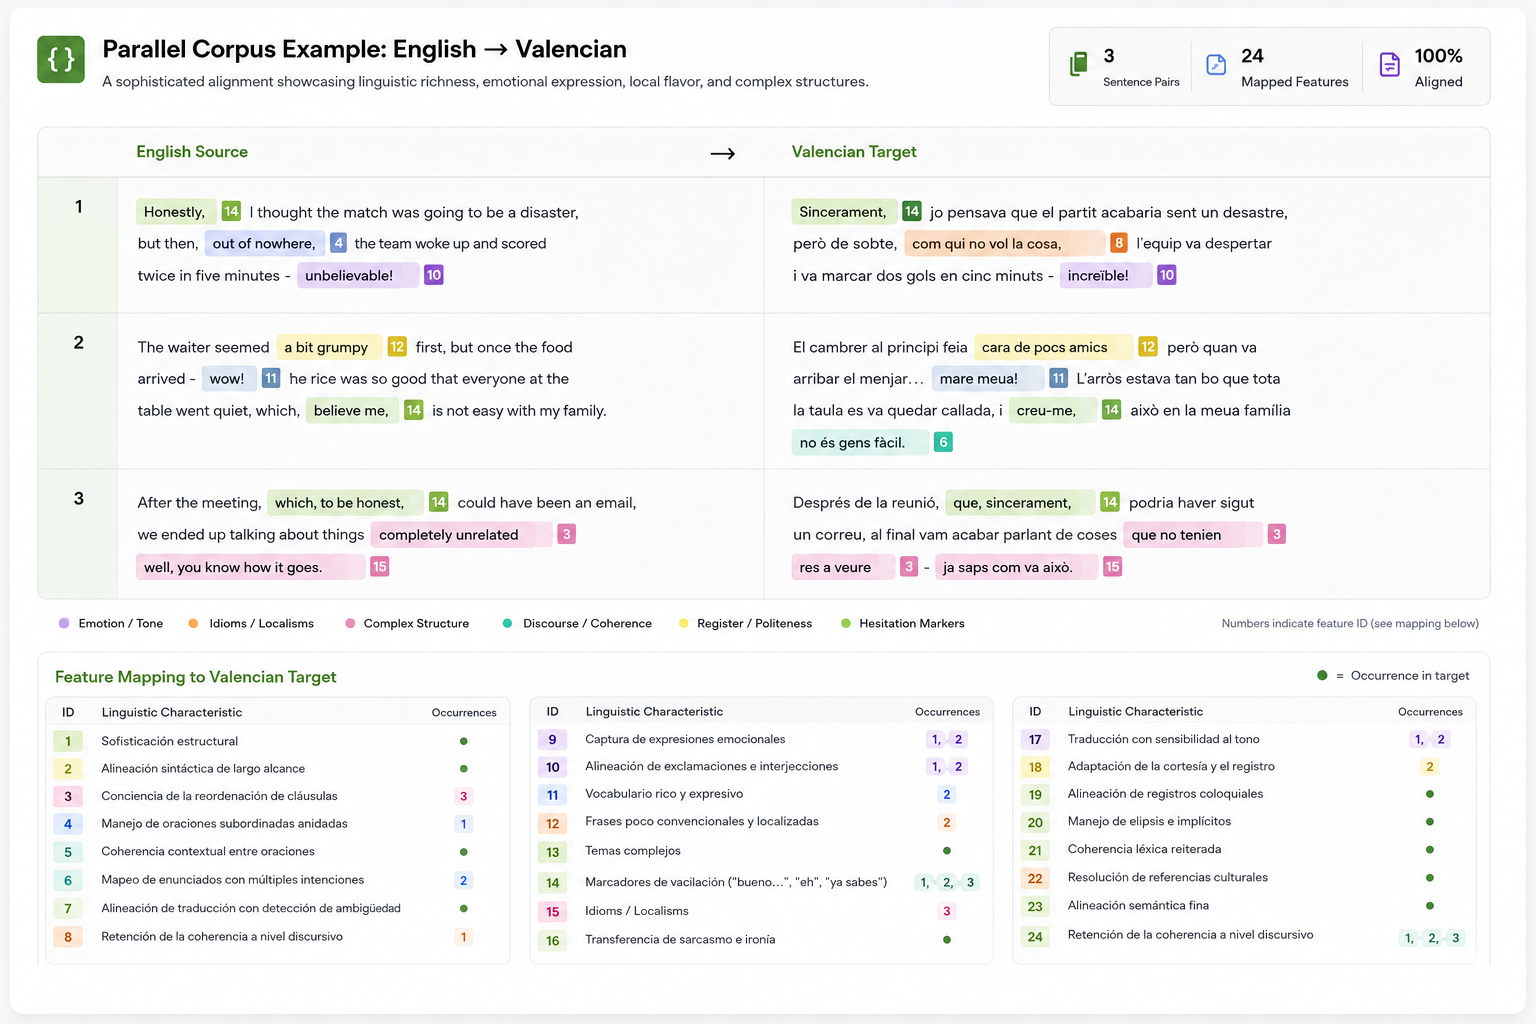
At Pangeanic, we treat parallel corpus creation and processing as a foundational discipline for multilingual AI. From multilingual data collection to precise alignment, through linguistic validation, terminology control, and data governance, every layer is designed to reduce noise and preserve semantic correspondence across languages.
The result is not just bilingual text, but a structured multilingual resource, ready to power machine translation, cross-lingual search and retrieval, language model adaptation, evaluation workflows, and AI systems deployed in production.
Access licensed parallel corpora in 50+ languages today
Pangeanic’s catalog offers commercially licensed parallel corpora built for multilingual AI agents, LLM fine-tuning, machine translation, search and retrieval, evaluation pipelines, and enterprise AI deployments. Choose ready-to-use corpora or request custom language combinations tailored to your domain.
English ↔ Spanish
High-volume aligned corpora for LLM fine-tuning, machine translation, and multilingual retrieval systems.
English ↔ German
Enterprise-grade corpora widely used for localization, terminology management, and machine translation adaptation.
English ↔ French
Large bilingual corpora for multilingual copilots, evaluation, and translation workflows.
English ↔ Italian
Curated corpora spanning enterprise, legal, and multilingual customer interaction domains.
English ↔ Arabic
High-demand corpora for multilingual AI systems serving Middle East and North Africa markets.
English ↔ Chinese
Strategic bilingual datasets for multilingual LLMs and enterprise AI applications.
Looking for another language pair?
Explore our catalog of 50+ languages or request custom-built parallel corpora designed for your domain, terminology requirements, and deployment environment.
What are parallel corpora, and why are they essential for multilingual AI?
Parallel corpora are structured collections of translated texts aligned at the sentence or segment level across two or more languages. They are indispensable for machine translation, multilingual AI, language model adaptation, and evaluation, because they show how meaning, terminology, and structure correspond from one language to another.
Their importance grew with the rise of statistical and then neural machine translation, where alignment quality directly shapes model performance and behavior. Today, these datasets go far beyond translation: they support multilingual language models, text generation, cross-lingual search and retrieval, and enterprise AI evaluation workflows.
Public resources, such as parliamentary proceedings or institutional corpora, provide a useful foundation. But they are often limited to certain domains and require extensive cleaning, filtering, and normalization. In production environments, the value of parallel data does not depend on availability alone. It depends on alignment accuracy, domain relevance, terminology consistency, and operational readiness.
Why do advanced translation systems still need parallel corpora?
Parallel corpora remain essential because even the most advanced translation systems need reliable, traceable bilingual data. They provide aligned source and target texts, which are indispensable for model adaptation, terminology control, quality evaluation, coverage of specialized domains, deployment in private environments, and continuous improvement with human validation.
At Pangeanic, we design, process, and operate parallel corpora at industrial scale for machine translation, multilingual AI, and public-sector language infrastructure. In 2020, Slator reported that Pangeanic had passed the 10 billion mark in aligned data segments across 84 languages. European projects such as NTEU also involved large-scale corpus building, data pooling, and publication across EU language combinations, contributing to neural translation engines and reusable multilingual resources.
Model training and adaptation
Even the strongest pretrained systems need adaptation for legal, medical, financial, technical, or media content. Parallel corpora let models learn the terminology, style, and translation patterns specific to an organization, domain, or industry.
Translation quality evaluation
Translation quality is not measured by output fluency alone. Evaluation requires reference translations, human judgment, and metrics that compare the source text, the model output, and the expected translation in the target language.
Terminology consistency
Enterprises need translations that are not only correct, but consistent. Product names, legal terms, safety instructions, and brand language must be rendered uniformly across all documents, markets, and channels.
Low-resource languages and specialized domains
Generic translation systems struggle when language coverage is limited or when content belongs to a specialized professional domain. Carefully selected, cleaned, and validated parallel corpora provide the data needed to extend coverage and produce more reliable results.
Data control and confidentiality
Regulated organizations cannot always send sensitive text to external translation APIs. Internal parallel corpora let them improve private systems while keeping control over content, access, data retention, and governance.
Continuous improvement loops
Human corrections, reviewer feedback, and approved translations become new aligned examples. Over time, this improvement loop strengthens translation quality, terminology accuracy, and model reliability.
Sources: Slator article on Pangeanic passing 10 billion aligned data segments; Pangeanic information on the NTEU project; the OPUS open parallel corpus collection; the WMT General Machine Translation shared task; and research on COMET and machine translation evaluation using the source text, machine output, and reference translations. Slator, NTEU, OPUS, WMT, COMET.

What turns a parallel corpus into production-ready training data?
A parallel corpus becomes production-ready training data when its translated texts are aligned, verified, cleaned, annotated, documented, and prepared for a specific model or workflow. Its value depends not only on segment volume, but also on alignment quality, domain relevance, language coverage, metadata, provenance, and whether it can be safely reused in production systems.
At Pangeanic, we structure parallel corpora as part of broader multilingual data operations. This approach covers corpus selection and acquisition, translation memory cleaning, bilingual alignment, linguistic review, terminology control, metadata preparation, data governance, and integration into machine translation, multilingual AI, and evaluation workflows. It builds on large-scale operational experience, including passing the 10 billion alignment milestone and taking part in European projects such as NTEU.
Alignment quality
A parallel corpus is only as reliable as the alignment between source and target text. Sentence- and segment-level correspondence must preserve meaning, terminology, structure, and context, especially when the data is used to train or evaluate translation systems.
Linguistic verification
Human review remains essential, because aligned data can contain omissions, mistranslations, formatting noise, duplicates, or inconsistent terminology. Linguistic verification turns raw bilingual material into reliable training data.
Scale and availability
Effective multilingual AI needs volume, but usable parallel data remains scarce for many languages and domains. Corpus operations therefore require selection, cleaning, deduplication, and controlled expansion of data across the language pairs and industries that matter for the model.
Domain relevance
A corpus of legal contracts, medical content, software strings, administrative documents, or customer support content cannot be treated as a set of interchangeable texts. Domain relevance determines whether a model learns useful translation behavior or just generic language patterns.
Linguistic diversity
Translation data must reflect linguistic variation across regions, registers, document types, and use cases. This helps models handle multilingual environments where the same language can vary by market, audience, language variety, and professional context.
Operational governance
Corpora used in production systems need clear rules for provenance, access, filtering, retention, review, and reuse. Rigorous governance lets multilingual data support training, evaluation, and deployment without exposing sensitive content or creating uncontrolled data flows.
Sources: Slator article on Pangeanic passing 10 billion aligned data segments; Pangeanic information on the NTEU project; the OPUS open parallel corpus collection; and OPUS-related research on aligned multilingual datasets. Slator, NTEU, OPUS, OPUS research paper.

Parallel corpora delivered at industrial scale for multilingual AI
Global technology leaders trust us with mission-critical multilingual data operations at scale.
Microsoft
Pangeanic built more than 50 million aligned segments across 20+ languages, with a particular focus on low-resource language environments. The project combined scale, linguistic precision, and accelerated turnaround to support the training of multilingual AI models built for production environments and used by millions of people.
Confidential client
For a NASDAQ Top 10 company, Pangeanic developed more than 45 million segments across 27 languages and several operational domains. The data was designed for multilingual AI and translation model development, strengthening the linguistic consistency of a strategic translation system used by millions of people.
Amazon
Pangeanic generated more than 10 million aligned segments in two languages, demonstrating deep linguistic expertise and operational rigor for targeted language pairs. The project showed Pangeanic’s ability to maintain quality and consistency at scale across the entire parallel corpus creation process.
FAQ
Parallel corpora for LLMs, machine translation, and multilingual AI
This FAQ explains how parallel corpora are collected, evaluated, filtered, and used in modern language systems. The same principles apply to machine translation, multilingual language models, search and retrieval workflows, evaluation pipelines, and governed enterprise AI systems.
What metrics are used to evaluate the quality of a parallel corpus?
Parallel corpus quality is evaluated through several criteria: alignment accuracy, language identification, noise detection, duplicate removal, domain consistency, terminology fidelity, lexical coverage, and downstream translation performance. For machine translation, reference-based metrics such as BLEU and neural metrics such as COMET can be used alongside human review to measure how much the corpus improves translation in real tasks.
How do neural methods use parallel corpora to learn multilingual representations?
Neural models use parallel corpora to learn how the same meaning is expressed across languages. Parallel sentences can support translation objectives, contrastive learning, multilingual embeddings, and translation language modeling. This helps models connect equivalent meanings across languages and improves their performance in multilingual search, classification, translation, and generation.
What are the main challenges in collecting parallel data at scale for LLM training?
The main challenges are data scarcity, noise, alignment errors, wrong language pairs, duplicated content, boilerplate text, inconsistent terminology, and uneven domain coverage. Data mined from the web can provide volume, but it usually requires language detection, sentence matching, filtering, deduplication, human review, and domain balancing before it becomes reliable training data.
Why are parallel corpora useful for LLMs if LLMs are not only translation systems?
Parallel corpora help LLMs learn multilingual equivalence, terminology consistency, and meaning preservation across languages. They are useful for translation, multilingual instruction tuning, cross-lingual search and retrieval, evaluation datasets, preference data, domain adaptation, and controlled generation in regulated multilingual environments.
How does Pangeanic differentiate in building parallel corpora?
At Pangeanic, we structure parallel corpora as governed multilingual data pipelines, not as static bilingual datasets. The process combines controlled selection and sourcing, precise alignment, data cleaning, human linguistic review, terminology validation, metadata preparation, governance, and integration into machine translation, LLM, and evaluation workflows. This approach builds on our industrial corpus experience, including passing the 10 billion alignment milestone and EU projects such as NTEU.
When should an enterprise build its own parallel corpus?
An enterprise should build or curate its own parallel corpus when generic translation systems fail to reflect its terminology, risk profile, privacy needs, document types, or regional language requirements. Private corpora are especially useful for legal, medical, financial, government, technical, and customer support content, as well as other regulated content.
Sources: Slator article on Pangeanic passing 10 billion aligned data segments; Pangeanic information on the NTEU project; research on COMET and neural machine translation evaluation; work on XLM and translation language modeling; work on LASER and multilingual sentence representations; and ParaCrawl information on large-scale parallel corpus mining. Slator, NTEU, COMET, XLM research, LASER research, ParaCrawl.
PECAT for parallel corpus creation and management
PECAT is Pangeanic’s platform for orchestrating multilingual and multimodal data operations. For parallel corpora, it manages bilingual data selection and sourcing, segment alignment, annotation, quality control, terminology validation, and governance within a single operational process.
This approach matters because building a parallel corpus is not just a translation task. It is a data engineering and linguistic validation workflow in which every segment must remain traceable, reviewable, and usable for machine translation, LLM fine-tuning, evaluation, and the deployment of multilingual AI systems.
Parallel data sourcing and preparation
At Pangeanic, we use PECAT to coordinate the selection, sourcing, preparation, and control of bilingual and multilingual data. The platform structures ingestion by language, domain, format, and the specific requirements of each project.
- Collection of multilingual content from curated, proprietary, and institutional sources
- Data sourcing for legal, medical, technical, public-sector, and enterprise domains
- Bilingual data preparation for translation memories, training corpora, and model workflows
- Controlled ingestion, project dashboards, vendor management, and production tracking
- Secure handling of sensitive content, with anonymization workflows where required
Alignment, annotation, and review
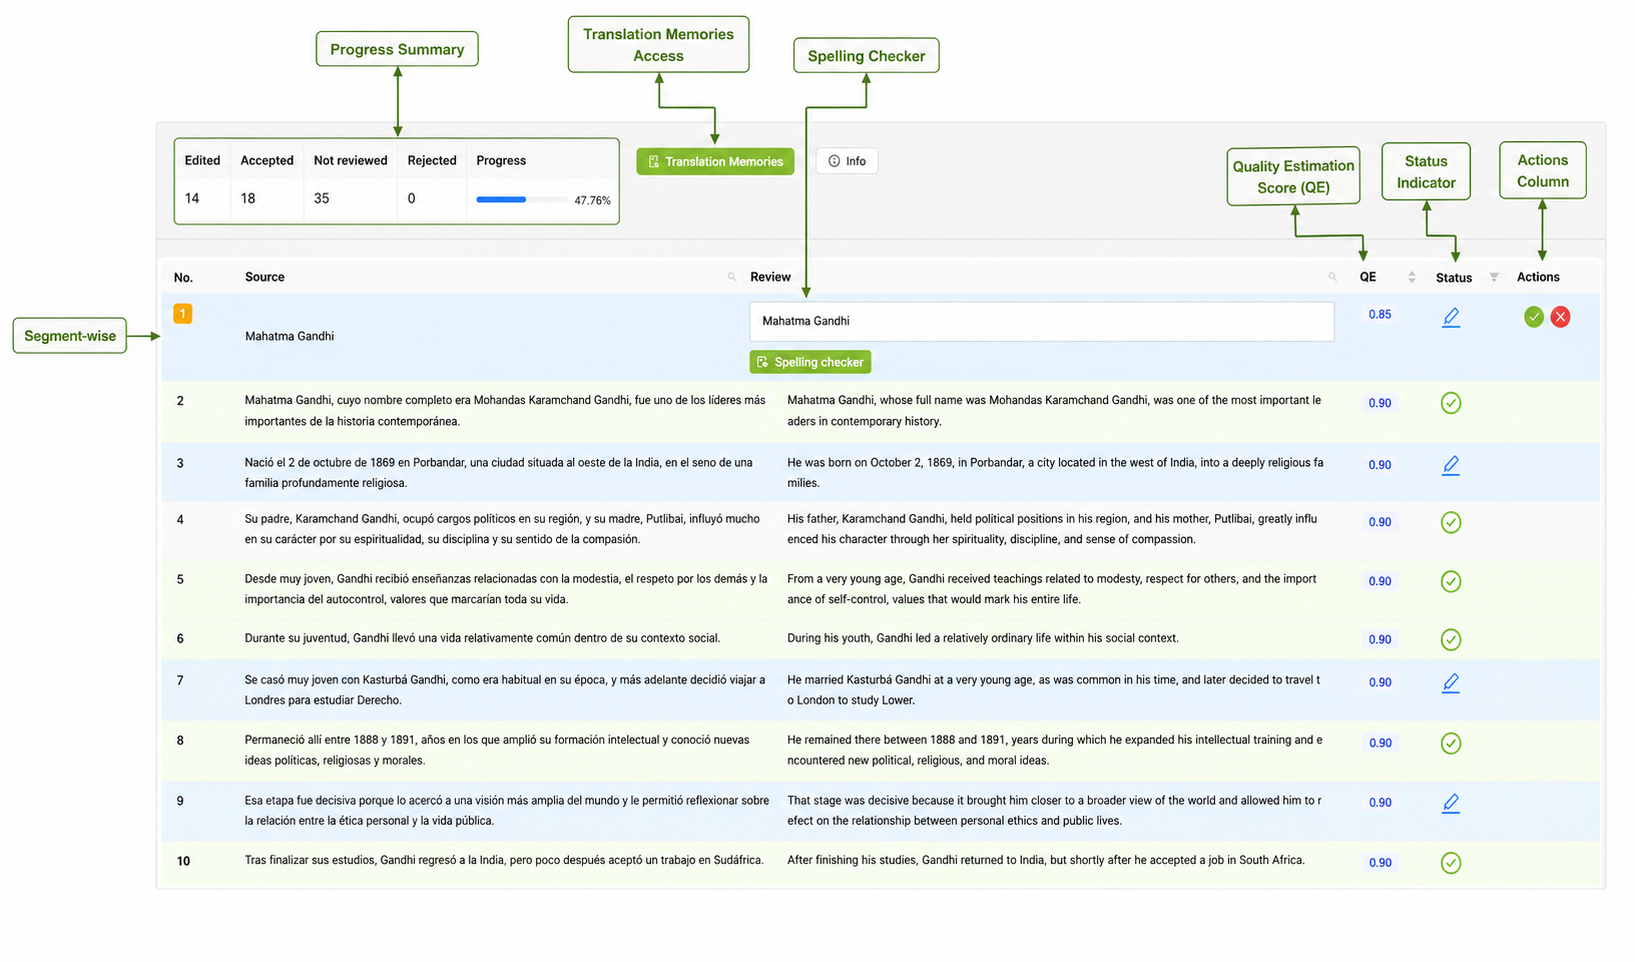
PECAT manages the preparation and control phase in which source and target segments are aligned, verified, annotated, and prepared for machine translation and multilingual AI systems. Automated checks are combined with expert human review to preserve meaning, terminology, and dataset integrity.
- Sentence and segment alignment across language pairs
- Terminology enrichment, metadata, and tagging for corpus control and reuse
- Glossary and regular expression (regex) support to improve annotation accuracy
- Human review combined with automated quality checks and AutoQA
- Quality reports that ensure traceability, auditability, and continuous improvement
Sources: Pangeanic information on the PECAT platform and text annotation services. PECAT platform, text annotation services.
Data operations backed by recognized quality standards
Our data and language technology operations rely on certified management systems for quality, translation services, information security, medical device quality management, and human post-editing of machine translation output. These frameworks govern PECAT workflows so they remain consistent, secure, auditable, and reliable in production environments.
Sources: official ISO information on quality management, translation services, information security, medical device quality management, and human post-editing of machine translation output. ISO 9001, ISO 17100, ISO/IEC 27001, ISO 13485, ISO 18587.
Parallel corpus data lake
Large-scale parallel corpora for multilingual AI and machine translation
At Pangeanic, we deliver large-scale parallel corpora and multilingual AI training datasets from a repository of more than 10 billion aligned segments, complemented by custom data operations tailored to each model, domain, and language pair. Every project rests on data quality, linguistic precision, terminology control, and governed, production-ready delivery.
Explore related datasets
Multilingual data collection, human review, structured metadata, and governed delivery pipelines for enterprise and public-sector production environments.