

3 min read
Pangeanic Joins Mozilla Data Collective as an AI Training Data Provider
AI TRAINING DATA· DATASET LICENSING· MOZILLA DATA COLLECTIVE Pangeanic Joins Mozilla Data Collective as an AI Training...
Datasets for AI · Speech · Clinical
Pangeanic produces and licenses clinical conversation data (audio, verbatim transcripts, and metadata) for teams that train and evaluate ambient scribes, medical speech recognition, and clinical voice agents. Our core offer is simulated consultations recorded by practicing physicians in realistic acoustic conditions, including telemedicine, complemented by real recordings where the rights are clear. Every hour is labeled as real, simulated, or synthetic.
The buying problem
Of course, the data exists. Millions of consultations take place every day. But a recording of a real patient describing symptoms is health data, a special category under the GDPR and protected health information under HIPAA, so it cannot simply be collected, pooled, and licensed. The corpora that do reach industrial scale sit inside the companies that recorded them. The public alternatives are small, mostly English, and mostly simulated, and the published research says so openly.
That leaves most AI teams buying from the open market, where the label on the box is the weakest part of the product. Role-played recordings are sold as "synthetic", machine-generated dialogues are sold as "conversations", and real recordings change hands without a consent trail. The risk in clinical speech data is rarely audio quality. It is not knowing what you bought.
Picture the scene. You license a large set of "doctor-patient conversations" and train on it. Six months later, your legal team asks which hours involved real patients, in which country they were recorded, and what those patients agreed to. If the vendor cannot answer per recording, neither can you.
WHAT THE PUBLISHED RESEARCH REPORTS
Full references in the Sources section below.
Provenance classes
For us at Pangeanic, the 3 terms are not interchangeable. Simulated means recorded by people. Synthetic means generated by a machine. Every hour we deliver carries one of these labels in its metadata and in the dataset datasheet.
| Class | What it is | Who speaks | Consent and privacy basis | Strongest use | Main limitation |
|---|---|---|---|---|---|
| Real | A recording of an actual consultation or telemedicine visit. | A practicing clinician and a real patient. | Sourced through local data partners. Accepted only after the permission chain is verified: collection basis, de-identification, onward licensing rights, and a legal basis that covers AI training. | Final evaluation and acceptance testing, where live clinical conditions and patient behavior matter most. | Availability depends on jurisdiction. In the European Union, rights are confirmed dataset by dataset. |
| Simulated | A consultation acted out by people from a clinical case brief, recorded as unscripted dialogue in acoustic conditions that reproduce real consultations. | Practicing physicians, recorded outside their working hours, with a briefed second speaker as the patient. | No patient is involved, so there is no patient health information and no patient consent chain. Speakers sign informed consent and a rights assignment, as in any voice recording. | Training and fine-tuning at volume, with balanced coverage of specialties, languages, accents, and recording settings. | Realism depends on the case design and the speakers. Poorly briefed role-play sounds scripted. |
| Synthetic | A conversation generated by a machine: text from a language model, audio from a speech synthesizer, or both. | Nobody. Voices and wording are model output. | No speaker consent is needed, but the license terms of the generating models apply. | Augmentation of rare terminology, drug names, and edge cases, always with human review. | Lacks natural turn-taking, disfluency, and room acoustics. Not a substitute for recorded speech in evaluation. |
What we deliver
Deliveries follow your technical specification. The components below are the standard structure of a Pangeanic clinical conversation dataset.
01 · AUDIO
Two-party clinical conversations recorded in telemedicine or in-room conditions, with sample rate, file format, and channel layout defined in your specification.
02 · TRANSCRIPTS
Human-verified transcripts that keep what was actually said, including disfluencies and medical terminology, prepared by native-language transcribers.
03 · METADATA
Structured metadata that lets you balance, filter, and split the dataset without listening to it.
04 · PRIVACY LAYER
Personal identifiers in real recordings are detected and removed or replaced in both audio and transcript, then checked by human reviewers.
05 · OPTIONAL ANNOTATION
Annotation is scoped per project and produced on PECAT, our annotation and review platform, by reviewers qualified for the domain.
06 · DOCUMENTATION
The document set that procurement, legal, and model governance teams ask for, delivered with the data.
Method
Simulated clinical conversations are a core part of our speech work, not a fallback. But a simulated consultation is only as useful as its case design, its speakers, and its acoustics. Indeed, this is where most role-played data fails, so the method is documented and delivered with the dataset.
01
Clinicians write case briefs by specialty: presenting complaint, history, patient profile, and the outcome of the visit. Briefs set the facts, never the wording.
02
The clinician role is recorded by practicing physicians outside their working hours. They know the terminology, the questioning routine, and how a consultation actually unfolds. Each speaker signs consent and a rights assignment.
03
Speakers conduct the consultation in their own words, in a consulting room or over a phone or video line, with the background noise of a real clinical setting. Nothing is read aloud.
04
Recordings are transcribed and reviewed against the guideline. The recording setting is verified from the signal itself (a telephone channel carries almost no energy above roughly 4 kHz), then each file is labeled and delivered with the datasheet.
Provenance and compliance
Clinical AI is deployed in regulated environments, and the training data is now part of the evidence. We document each dataset so that the answer to "where did this come from, and may we use it?" is a file, not a phone call.
Health data is a special category of personal data under Article 9 of the GDPR. A simulated consultation involves no patient, so the only rights to manage are those of any voice recording: the consent and the rights assignment of the speakers. That is what makes large, balanced, multilingual volumes feasible.
Real recordings come from local data partners, and each dataset is accepted only when 4 links are documented: the original collection basis, the de-identification, the onward licensing rights, and a consent or other legal basis that covers AI training. We would rather be conservative than represent material as available before the rights are clear.
Article 10 of the EU AI Act sets data governance requirements for high-risk AI systems, including the origin of the data and how it was collected. The datasheet and the per-recording provenance label are written to feed that documentation.
Pangeanic coordinated MAPA (CEF Action 2019-EU-IA-0013), which built a multilingual anonymization toolkit for public administrations with a focus on the medical and legal domains, and NTEU, which built neural machine translation for European public administrations.
Buyer checklist
These are the questions we expect in a request for information, and the ones we answer in writing before a contract is signed. They apply to any supplier, including us.
Read the buyer's guide to evaluating multilingual AI data services
Where it is used
Training and evaluation data for AI scribes that turn a consultation into a draft clinical note, where speaker roles and medical terminology must be right.
Conversational audio with overlap, accents, and domain vocabulary for speech recognition and speaker separation in clinical settings.
Dialogue data for intake, triage support, and follow-up agents that must handle how patients actually describe symptoms in each language.
FAQ
Clinical speech data is recorded spoken interaction from healthcare settings (in-person consultations, telemedicine visits, and clinical dictation), paired with transcripts and metadata. AI teams use it to train and evaluate medical speech recognition, speaker diarization, ambient clinical documentation, and clinical voice agents.
Real conversations are recordings of actual consultations, made with consent and de-identified before delivery. Simulated conversations are recorded by people (at Pangeanic, practicing physicians) who act out a consultation from a clinical case brief, so no patient is involved. Synthetic conversations are generated by a machine, as text from a language model, audio from a speech synthesizer, or both. Pangeanic labels every delivered hour with one of these 3 classes.
No. A simulated consultation is built from a fictional case brief and involves no real patient, so it contains no patient health information. The speakers' voices are still personal data, which is why each contributor signs informed consent and a rights assignment covering AI training and evaluation.
Yes, and public research already relies on them: ACI-Bench, PriMock57, and the OSCE simulated interview corpus are all built from simulated or mock consultations. Simulated data gives you controlled coverage of specialties, languages, accents, and acoustic conditions at a volume that real recordings rarely reach. What matters is the design: practicing physicians, unscripted dialogue, and recording conditions (consulting room, telephone or video telemedicine, background noise) that reproduce real consultations. Where real, de-identified recordings are available, we recommend reserving them for final evaluation so you can measure the result on your own task.
Yes, in some jurisdictions. Real recordings are sourced through local data partners, and each dataset is accepted only after its permission chain has been verified: the original collection basis, the de-identification, the onward licensing rights, and a consent or other legal basis that covers AI training. In the European Union, where health data is specially protected, availability is confirmed dataset by dataset, and we do not represent material as available before the rights are clear.
Simulated clinical consultations have been produced for multilingual programs covering French, Italian, German, Spanish, Ukrainian, Russian, and Dutch, as well as English, always with native-speaking clinicians. Further languages are scoped per project, and language, accent, and specialty coverage is confirmed in the dataset datasheet before delivery.
Each delivery includes the audio files, verbatim transcripts with speaker roles and timestamps, per-recording metadata, and a datasheet that states the provenance class, consent basis, license scope, and quality-control results. Optional layers such as de-identification tags, medical entity annotation, and speaker-disjoint training and test splits are added to specification.
Datasets are licensed for AI training and evaluation under terms that state the permitted uses, the territory, the duration, and whether the license is exclusive. Custom collections can be commissioned with exclusive rights. The license references the consent records, so the rights you receive match the rights the speakers granted.
Related
The full speech and audio offer: conversational, call center, and multilingual speech datasets, plus governed collection.
Explore speech datasets EvidenceThe European project Pangeanic coordinated to detect and transform sensitive information in medical and legal text.
See the project PlatformThe human-governed platform used for transcription, annotation, review, and traceable data operations.
See PECATSOURCES
Yim, W. et al. (2023). ACI-BENCH: a novel ambient clinical intelligence dataset for benchmarking automatic visit note generation. Scientific Data. pmc.ncbi.nlm.nih.gov/articles/PMC10482860
Fareez, F. et al. (2022). A dataset of simulated patient-physician medical interviews with a focus on respiratory cases. Scientific Data. doi.org/10.1038/s41597-022-01423-1
Korfiatis, A. P. et al. (2022). PriMock57: a dataset of primary care mock consultations. arxiv.org/abs/2204.00333
Evaluating Ambient Clinical Scribes in India: The Need for Multilingual Real-World Clinical Conversation Data (2026). arxiv.org/abs/2609.17355
Regulation (EU) 2016/679 (GDPR), Article 9. eur-lex.europa.eu/eli/reg/2016/679/oj
Regulation (EU) 2024/1689 (AI Act), Article 10. eur-lex.europa.eu/eli/reg/2024/1689/oj
MAPA, Multilingual Anonymisation Toolkit for Public Administrations, CEF Action 2019-EU-IA-0013. pangeanic.com/eu-funded-ai-language-technology-projects
Send your specification or your request for information. We reply with sample recordings, a draft datasheet, and a written answer on provenance class, consent, and license scope.
Speech datasets rarely arrive ready for production AI. Audio is often fragmented, acoustically inconsistent, unevenly transcribed, and missing the linguistic detail needed for reliable model training. Pangeanic approaches speech dataset creation as an infrastructural discipline: the careful assembly of existing catalog data and fully custom corpora aligned with the operational needs of speech recognition, speech synthesis, voice agents, and multilingual audio systems.
Speech data pipelines often break down before model training begins. The main constraints are not only data volume, but also acoustic variation, transcription quality, annotation discipline, consent, licensing, metadata, and governance. What appears to be abundant audio can still contain weak supervision, limited traceability, and inconsistent signals for training.
Speech data comes from varied environments where background noise, microphones, accents, speaking styles, and recording conditions differ widely. Without controlled collection and quality review, models can inherit variability that weakens performance in production use.
High fidelity transcription, speaker labeling, intent annotation, emotion labels, timestamps, and linguistic review require consistent guidelines and trained reviewers. Misaligned labels or superficial tagging introduce errors that compound across training and evaluation cycles.
Speech data can carry personally identifying signals, especially when voice is used for speaker identification or user recognition. Licensing, consent, provenance, retention rules, and audit trails are conditions for deploying audio models in regulated environments.
Sources: Mozilla Common Voice on multilingual speech datasets; Datasheets for Datasets on dataset documentation and transparency; and European Data Protection Board guidance on voice data and biometric identification. Mozilla Common Voice, Datasheets for Datasets, EDPB voice assistant guidance.
Pangeanic structures speech data collection as a controlled, ethical, and linguistically grounded operation. Acquisition, annotation, consent, licensing, metadata, and quality review are managed together so that speech datasets can support speech recognition, speech synthesis, voice agents, and conversational AI in production environments.
Speech datasets can be collected through PECAT, dedicated applications, and controlled contributor workflows where participants record guided prompts. Collection should include documented consent, clear licensing, contributor instructions, data provenance, and review steps before the audio is used for model training.
Beyond scripted audio, spontaneous speech can be collected and transcribed to capture natural pauses, interruptions, accents, repairs, informal wording, and conversational variation. This helps train systems that must operate beyond clean laboratory conditions.
Speech data for less represented languages requires controlled sourcing, local linguistic knowledge, speaker diversity, and legal clarity. The goal is to improve language inclusion while maintaining audio quality, transcription accuracy, and responsible data use.
Speech datasets should cover the sound patterns, pronunciation variants, and phonetic distribution of each language. This supports more robust speech recognition, more natural speech synthesis, and better performance across accents, speakers, and recording contexts.
Voice activated systems need trigger phrases, commands, and intent examples recorded across speakers, demographics, accents, and acoustic conditions. This helps reduce false rejection, improve responsiveness, and support safer interaction with voice agents.
Audio data should include varied microphones, distances, rooms, background noise, and recording devices. This helps models recognize speech reliably in realistic settings, from quiet offices to mobile, vehicle, call center, and public environments.
Pangeanic supports speech data collection, transcription, annotation, metadata preparation, and governed delivery for each project’s model requirements. Speech datasets can be structured for automatic speech recognition, speech to text, text to speech, call center analytics, automotive voice assistants, multilingual voice agents, and multimodal AI systems.
| Capability | Specifications | |
|---|---|---|
| Audio use cases | • Automatic speech recognition • Speech to text • Text to speech |
• Call center voice analytics • Automotive voice assistants • Multilingual voice agents |
| Audio file formats | • WAV • FLAC |
• MP3 • NIST SPHERE |
| Sampling rates | • 8 kHz for telephony data • 16 kHz for common speech recognition workflows |
• 44.1 kHz to 48 kHz for high fidelity audio and speech synthesis |
| Bit depth | • 16 bit • 24 bit |
• 32 bit floating point audio when required |
| Channel configuration | • Mono • Stereo |
• Multichannel audio for beamforming and microphone array use cases |
| Metadata fields | • Environment: studio, office, public, or natural setting • Device and channel: telephone, mobile, headset, or microphone array • Speaker attributes when legally permitted |
• Audio duration, bitrate, and sampling rate • Noise and signal to noise conditions • Linguistic data such as domain, intent, sentiment, and entities |
| Annotation types | • Word and phoneme time stamps • Sentiment and intent labels • Entity annotation |
• Speaker diarization • Speaker turns • Acoustic event labels |
| Compliance and governance | • GDPR aligned processing • CCPA aware workflows • ISO IEC 27001 information security controls |
• Consent records • Licensing and provenance • Retention, access, and audit rules |
| Compression parameters | • Configurable encoding settings • Format selection by model requirement |
• Delivery aligned with downstream training, evaluation, or deployment constraints |
Sources: Mozilla Common Voice on multilingual speech datasets; NIST SPHERE file format documentation; ISO IEC 27001 information security management; and European Data Protection Board guidance on voice data and responsible data processing. Mozilla Common Voice, NIST SPHERE, ISO IEC 27001, EDPB voice assistant guidance.
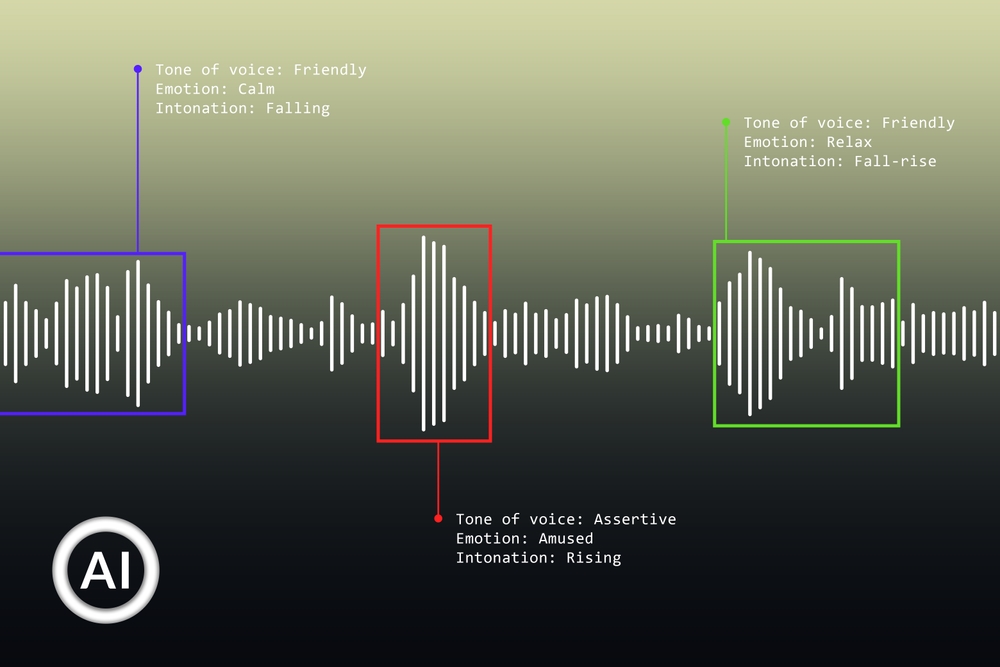
Pangeanic’s speech data pipelines have been deployed in environments where transcription accuracy, multilingual consistency, accessibility, and regulatory control are structurally required. These use cases show how speech data collection, transcription, speaker processing, human review, metadata enrichment, and privacy controls can become operational infrastructure for public institutions and AI systems.
Human reviewed transcription and subtitling workflows help preserve verbatim accuracy across Spanish and Valencian. Validation steps support institutional tone, accessibility, and searchable legislative archives.
AI supported transcription with expert linguistic validation helps process parliamentary discourse across Spanish, Catalan, Galician, and Basque while preserving legal integrity, traceability, and institutional precision.
More than 2,000 hours of multilingual audio were processed through segmentation, timestamps, transcription, speaker diarization, named entity annotation, personal data anonymization, and metadata enrichment.
Sources: Pangeanic use cases on Valencian Parliament transcription, Spanish National Parliament multilingual transcription, and comprehensive speech data processing for AI. Valencian Parliament, Spanish National Parliament, speech data processing for AI.
From raw audio to structured acoustic intelligence, PECAT supports speech data annotation, transcription review, metadata preparation, quality control, and governed delivery for multilingual AI systems.
PECAT structures speech data workflows as a controlled environment where collection, transcription, annotation, validation, metadata, and quality review remain aligned. The result is not a set of isolated audio files, but a governed data pipeline designed for speech recognition, speech synthesis, voice agents, and multilingual AI systems.
PECAT supports distributed speech data acquisition through web and mobile workflows, helping teams expand language coverage, manage contributors, and capture acoustic variation across speakers, locations, devices, and recording environments.
Speech annotation in PECAT operates as a validation layer where transcription, segmentation, timestamps, speaker information, linguistic labels, and quality control are integrated into one reviewable workflow.
Sources: Pangeanic PECAT platform information and Pangeanic speech annotation information. PECAT platform, speech annotation services.
FAQ
Understand how speech datasets are collected, transcribed, annotated, reviewed, and governed before they can support speech recognition, speech synthesis, voice agents, conversational AI, and multilingual audio models.
Speech data quality constrains model performance because audio models learn from acoustic signals, transcripts, labels, and metadata. Background noise, inconsistent microphones, weak transcription, missing speaker labels, and poor metadata reduce signal reliability. More data cannot compensate for poorly structured training evidence.
Annotation defines the learning signal for transcription, speaker diarization, timestamps, intent labels, sentiment labels, acoustic events, and linguistic metadata. Accurate and consistent annotation helps models interpret speech patterns, separate speakers, identify meaning, and generalize across languages, accents, and recording environments.
Human review is still required because automated pipelines cannot fully resolve accents, overlapping speech, ambiguous words, domain terminology, speaker changes, or contextual nuance. Expert validation helps correct errors, resolve disagreement, and keep outputs aligned with operational, linguistic, and regulatory requirements.
Speech datasets should include metadata for language, locale, speaker attributes when legally permitted, recording environment, device type, channel, duration, sampling rate, noise conditions, consent status, licensing, domain, task, and annotation guidelines. Metadata improves traceability, filtering, evaluation, and responsible reuse.
An enterprise should build a custom speech dataset when public or catalog data does not match its languages, accents, acoustic conditions, industry terminology, privacy requirements, voice agent workflows, or evaluation needs. Custom speech data is especially useful for call centers, automotive systems, public services, health care, media archives, and regulated sectors.
Pangeanic structures speech data collection, transcription, annotation, validation, metadata preparation, and governance as a single operational system. Human expertise, PECAT workflows, linguistic review, privacy controls, and quality management processes work together to support traceability, multilingual consistency, and production use.
Pangeanic’s speech data, language, and AI data operations are supported by certified management systems for quality, translation services, information security, medical device quality processes, and human review of machine translation output. These standards help ensure that PECAT workflows for speech collection, transcription, annotation, review, and governed delivery remain consistent, secure, auditable, and reliable in production environments.
Sources: ISO information on quality management, translation services, information security, medical device quality management, and full human review of machine translation output. ISO 9001, ISO 17100, ISO IEC 27001, ISO 13485, ISO 18587.
SPEECH DATA AT SCALE
Pangeanic supports speech data collection, transcription, translation, annotation, metadata preparation, and governed delivery through PECAT. From controlled acquisition to validated datasets, each workflow is aligned with language coverage, acoustic conditions, model objectives, consent requirements, and production AI constraints.
Explore related datasets
Multilingual collection, transcription review, speaker annotation, structured metadata, consent records, and governed delivery pipelines designed for production AI environments.
Yash Dhobale: Jul 31, 2026
Manuel Herranz: Jul 31, 2026
Manuel Herranz: Jul 29, 2026